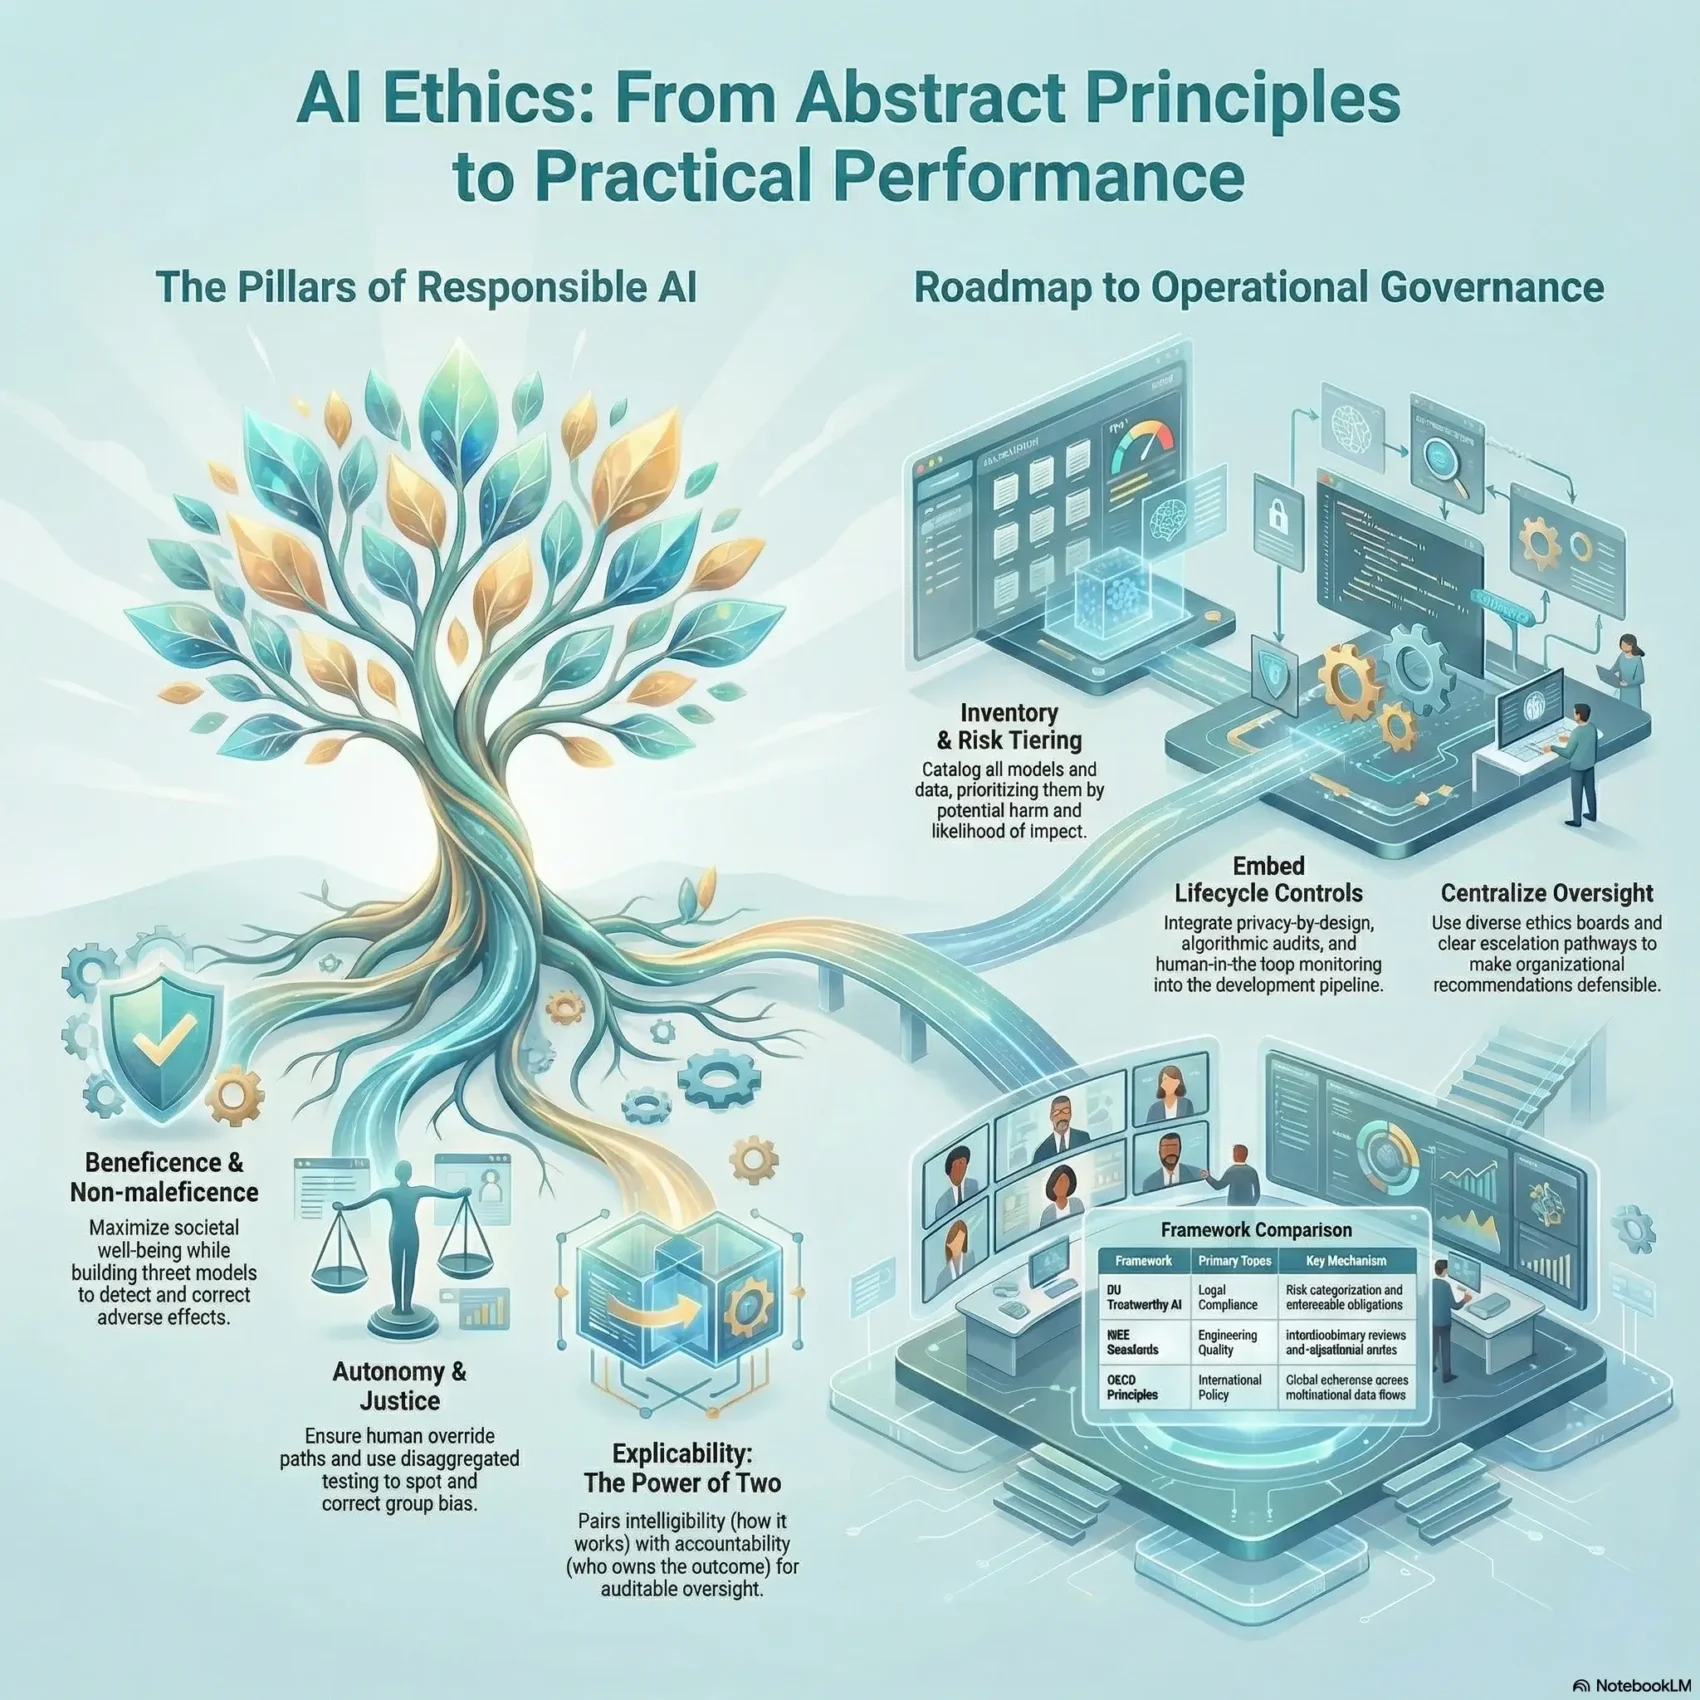
An AI ethics framework is a written set of principles, rules and checks that decides how your organisation builds and uses AI systems. It answers three practical questions: what you will not build, who signs off before a system goes live, and how you prove afterwards that it behaved as promised.
The need is no longer theoretical. McKinsey’s State of AI in 2026 survey covered 1,719 respondents across 97 countries. Nearly nine in ten said their organisation uses AI regularly in at least one business function. 44 percent said it is scaled across the enterprise. Meanwhile the first binding rules arrived: parts of the EU AI Act have applied since February 2025, and its transparency duties for AI-generated content have applied since 2 August 2026.
This guide shows how to get from values to working controls. It starts from the five principles researchers found underneath most published ethics codes. It then maps them onto the three reference models companies actually build on: the EU AI Act, the NIST AI Risk Management Framework and ISO/IEC 42001.
Key Takeaways
- Most published AI ethics codes reduce to five principles: beneficence, non-maleficence, autonomy, justice and explicability.
- Principles only matter once they become acceptance criteria, named owners and monitoring thresholds.
- Three reference models cover almost every need: the EU AI Act (law), NIST AI RMF (voluntary method) and ISO/IEC 42001 (certifiable management system).
- EU high-risk obligations were postponed to December 2027, but prohibitions, AI literacy and content transparency duties already apply.
- In the United States, state laws in Colorado, Texas, Illinois and New York City are the rules that bind employers today.
What an AI ethics framework actually is
Think of the framework as the bridge between a policy document and a line of code. On one side sit values such as fairness and privacy. On the other sit the things an engineer can build and test: a dataset check, a confidence threshold, a human review step, a log entry.
Without that bridge you get the common failure mode: a published set of commitments that nobody can point to in a release decision. The framework’s job is to make each commitment checkable by someone other than its author.

From principles to system requirements
Four moves turn a principle into something a team can act on.
- Make the value measurable. “Fairness” becomes a rule such as: selection rates for each protected group must stay within an agreed band, tested on a representative sample before every release.
- Name the owner. One person signs off the release, and that name is recorded. Shared responsibility means no responsibility.
- Set requirements by context. A model that ranks job applicants needs tighter controls than one that groups support tickets. Same principle, different thresholds.
- Write down the evidence. Dataset documentation, a model card and monitoring records are what let you answer a question six months later.
The result should be boring: a short list of gates every AI project passes through, with the same vocabulary for product managers, engineers and lawyers. Our guide to building an AI governance model covers how to structure that in an existing organisation.
Why there are so many principle lists, and how to stop worrying about it
If the field feels crowded, that is because it is. In a 2019 paper in the Harvard Data Science Review, Luciano Floridi and Josh Cowls compared six prominent sets of AI principles. The six included the Asilomar AI Principles, the Montreal Declaration, IEEE’s Ethically Aligned Design and the Partnership on AI tenets. Across them the authors counted 47 individual principles, with heavy overlap.
Their conclusion is the useful part: the overlap means you do not need to choose a camp. Map the terminology you encounter onto one short internal list, and treat the rest as synonyms.
Three habits keep this manageable:
- Keep a single register of the external codes and laws that apply to you, with a note on which internal control satisfies each one. Auditors and customers ask the same questions repeatedly, and the register answers them once.
- Use one intake form for new AI projects, so concerns arrive as requirements rather than as opinions in a meeting.
- Give executives a one-page summary and keep the detailed mapping with risk and compliance. Different audiences, same underlying document.
For the decision side of this work, see our practical guide to AI decision making, which covers how managers use model output without handing over the judgement.
The five principles that most frameworks agree on
Floridi and Cowls distilled those 47 principles into five. Four are borrowed from medical ethics, where they have been in use for decades. The fifth was added because AI creates a problem medicine did not have.
Beneficence and non-maleficence: benefit and harm
Beneficence asks who gains and by how much. In practice that means writing down the expected benefit before you build, in a form you could later measure. “Cuts average handling time in the returns queue” is a claim you can test. “Drives operational efficiency” is not.
Non-maleficence asks who could be hurt. The working method is a threat model: list the ways the system could produce a bad outcome, including misuse, then decide which of those you will detect and how quickly. A model that occasionally suggests the wrong warehouse shelf needs less protection than one that flags a customer as fraudulent.
Autonomy and justice: human control and fairness
Autonomy means a person stays in charge of whether and when to delegate a decision. Two things make it real: a documented override path, so a human can reverse an individual outcome, and a rollback path, so you can switch a model off without stopping the business. If nobody has tested the rollback, you do not have one.
Justice means measuring outcomes across the groups a decision affects, not just overall accuracy. A hiring model can be 92 percent accurate overall and still reject qualified candidates from one group at twice the rate of another. You only see that if you break the results down. Our article on AI hiring bias goes through the testing methods in detail.
Explicability: understandable and accountable
Explicability is the principle medicine did not need, and it has two halves. Intelligibility means someone can explain how a decision arose. Accountability means someone is answerable for it. Both are required: an explanation with no owner changes nothing, and an owner who cannot explain the decision cannot defend it.
For higher-stakes uses, this often means choosing a simpler model you can explain over a slightly more accurate one you cannot. Our guide to explainable AI covers the trade-off and the techniques.
Three reference models: EU AI Act, NIST AI RMF and ISO/IEC 42001
You do not need to invent a framework. Three published models cover most requirements, and they are complementary rather than competing.
Where they agree
All three expect the same core: risk assessment before deployment, documentation of data and model behaviour, human oversight of consequential decisions, testing for robustness and bias, and monitoring after launch. If you build those five capabilities, you are most of the way towards any of them.
Where they differ
- The EU AI Act is law. It sorts systems into risk tiers and attaches binding duties to each tier, with extraterritorial reach: it can apply to a company outside the EU whose system is used there. Our EU AI Act compliance guide works through the tiers and deadlines.
- NIST AI RMF is a voluntary method. Published by the US National Institute of Standards and Technology in January 2023, it organises the work into four functions: Govern, Map, Measure and Manage. It is sector-agnostic and scales down to small teams. It carries no legal force by itself, but Texas law now treats alignment with it as a mitigating factor.
- ISO/IEC 42001 is a certifiable standard. Published in December 2023, it defines an AI management system in the same style as ISO 27001 for information security: leadership commitment, a written AI policy, lifecycle risk assessment, data governance and continuous improvement. Because an accredited auditor can certify you against it, it is the version customers and procurement teams can verify.
Which one to build on
A simple rule works for most companies. If you sell into or operate in the EU, the AI Act sets your floor, because it is the only one that can fine you. Use NIST AI RMF as the internal method for getting there, because it describes how to do the work rather than what to achieve. Add ISO/IEC 42001 certification when customers start asking for proof, which in practice happens once you sell to enterprises or the public sector.
The rules that actually apply in 2026
This is the part of most ethics guides that ages fastest, so here is the state of play rather than a forecast.
Europe: what is live and what was postponed
The EU AI Act entered into force in August 2024 and applies in stages. Two things changed the timetable in 2026. EU institutions reached a provisional agreement on a Digital Omnibus package on 6 May 2026, confirmed by member states on 13 May, which postponed the heaviest obligations.
What that means concretely:
- Already applying: the prohibitions on unacceptable-risk uses (since February 2025), the AI literacy duty on employers, and the rules for general-purpose AI models (since August 2025).
- Applying since 2 August 2026: the transparency duties in Article 50. If people interact with an AI system, they have to be told, and AI-generated content has to be labelled. Watermarking for systems already in service got a grace period to 2 December 2026.
- Postponed: obligations for high-risk systems listed in Annex III, such as those used in employment, education and credit, moved from 2 August 2026 to 2 December 2027. Annex I high-risk systems, embedded in regulated products, moved to 2 August 2028.
The postponement is a delay, not a cancellation, and the underlying requirements did not change. Companies that used the original 2026 date for planning now have more time to finish the same work. Our overview of AI regulation in 2026 tracks the wider picture.
United States: state law does the work
There is no comprehensive federal AI statute, so the binding rules come from states. Four matter most for employers:
- Colorado (SB 24-205) took effect on 30 June 2026 after a delay from February. Deployers of high-risk systems need a risk management policy, impact assessments and notice to the affected person. They also need an appeal route to a human reviewer, plus notification to the Attorney General within 90 days of discovering algorithmic discrimination.
- Texas (TRAIGA, HB 149) took effect on 1 January 2026. It targets intentional harmful use rather than all AI, and offers a safe harbour for organisations that substantially align with the NIST AI RMF or a comparable standard.
- Illinois (HB 3773) took effect on 1 January 2026. It amends the state Human Rights Act so that discriminatory use of AI in employment decisions is a civil rights violation, and it requires employers to notify employees when AI is used in those decisions.
- New York City (Local Law 144) has applied since 2023. Automated employment decision tools need an annual independent bias audit, with the results published.
At the international level, the OECD AI Principles remain the common reference point. Adopted in 2019 and updated in May 2024, they have been taken up by 47 countries plus the EU, and they shape the vocabulary that the EU, US and UN documents all use. They are not enforceable, but aligning to them makes cross-border conversations shorter.
For the employment side specifically, see AI hiring tools and what the law requires and our piece on algorithmic management.
Governance: who decides what
Governance is the unglamorous machinery that makes the framework survive contact with a deadline. It comes down to two things: a body with authority, and named people with defined jobs.
An ethics board that has real authority
A review board only works if it can say no. That requires a charter setting out its remit, who sits on it, what it decides, and how often it meets. Without decision rights it becomes an advisory group that teams route around.
Membership should include product, engineering, legal and security, plus at least one voice representing the people affected by the decisions. Small companies do not need a standing board: a named reviewer for high-risk projects and a quarterly review is a proportionate version. Our article on automation ethics boards covers how to set one up, and the AI ethics officer role describes when a dedicated owner is worth it.
Roles and escalation
Four ownerships are worth naming explicitly: the product owner for each system, model risk, privacy and security. Then write down the path a problem takes: who logs it, who investigates, who can pause a deployment, and at what severity it reaches an executive.
The test of an escalation path is whether a junior engineer knows how to use it. If reporting a suspected fairness problem means finding the right person to ask, it will not happen. A written AI governance policy is what closes that gap.
Controls across the AI lifecycle
Controls work best where the work happens, not in a separate compliance exercise at the end.
Design and data
Decide at the start what data the system may use, on what legal basis, and for how long. Record who can access each dataset and why, and enforce it with role-based access rather than trust.
GDPR in Europe and state privacy laws in the US set the baseline: clear notice, honoured user rights, recorded consent where consent is the basis. Our data governance strategy guide and privacy compliance framework cover the mechanics, and data privacy trends for 2026 tracks what changed.
Development and testing
Three checks belong in the pipeline before release. Write a model card, a short document stating purpose, training data, performance and known limits. Keep enough versioning that someone else can reproduce a result. And run the model against a test set built to surface failure, including adversarial inputs and edge cases, rather than the sample that made it look good.
Record what you found. A risk register that lists known weaknesses and what you did about them is more credible to an auditor than a claim that no weaknesses exist.
Deployment and monitoring
After launch, two things need watching: whether the model still performs as tested, and whether performance is even across groups. Both drift, because the world the model was trained on keeps changing.
Set alert thresholds rather than reviewing dashboards by habit, and define in advance what happens when one trips. For consequential decisions, keep a human in the loop and give affected people a way to contest the outcome. Our piece on AI in employee monitoring shows what happens when that oversight is missing.
Fairness and bias: making it measurable
Bias enters through data far more often than through code. A model trained on past decisions learns those decisions, including the ones the organisation would rather not repeat.
Four practices do most of the work:
- Curate the training data. Document where each dataset came from and check whether the groups affected by the decision are adequately represented. Fixing a model is harder than fixing its inputs.
- Assess impact before launch. Colorado now requires this for high-risk systems, and it is good practice regardless: write down who could be disadvantaged and how you would notice.
- Test by subgroup, repeatedly. One pre-launch fairness check is a snapshot. Schedule the same test on live data and watch the trend.
- Build a redress route. People need a way to challenge an outcome and get an answer in a reasonable time. This is now a legal requirement in several jurisdictions, and it doubles as your early warning system.
One caution on definitions. There are several mathematical definitions of fairness, and some of them cannot all be satisfied at once. Pick the definition that fits the decision, write down why, and be ready to explain the choice. Pretending there is one neutral answer is what gets organisations into trouble.
Transparency that people can use
Transparency fails in two directions: saying nothing, or publishing documentation nobody can read. The target is a disclosure that lets a non-expert make a sensible choice.
Since August 2026, EU rules require telling people when they are interacting with an AI system and labelling AI-generated content. That makes the minimum concrete. Beyond the minimum:
- State plainly where AI is used, what it decides, and how a human can be involved.
- Match the explanation to the audience. A regulator wants the model card. A customer wants to know why their application was declined and what to do next.
- Keep documentation current as models change. Stale documentation is worse than none, because it creates false confidence.
- Assign an owner for documentation quality, or it will drift.
Transparency has a limit worth respecting: explanations should not leak personal data or expose the system to gaming. Say what the decision rested on, not the exact thresholds someone could work around. Our article on AI ethics in the workplace covers what employees are owed here.
Privacy and security by design
Treat privacy and security as product requirements with release criteria, not as a review at the end.
The practical list is short. Collect the minimum personal data the job needs and delete it on a schedule. Grant least-privilege access to datasets, models and infrastructure, and log it. Encrypt in transit and at rest, and manage the keys properly. Write an incident response plan that covers AI-specific failures, not just data breaches.
AI adds two threats conventional security misses. Models can leak training data, which membership inference testing is designed to detect. And systems that read untrusted input are exposed to prompt injection, where instructions hidden in content hijack the model’s behaviour. Both need testing before scale-up, not after.
Generative AI: the newer risks
Foundation models, the large general-purpose models that sit behind most generative tools, create three problems that older systems did not.
Fabrication. Models produce fluent, confident text that is wrong. The mitigations are grounding the model in your own verified sources, citing what it drew on, and requiring human review where a wrong answer is expensive.
Misuse. A general tool can be pointed anywhere. Content filters, rate limits, a written acceptable-use policy and monitoring for abuse patterns cover most of it.
Provenance and rights. Where the training data came from, and who owns the output, are still being litigated. The defensive position is to document the lawful basis for data you use, label synthetic media, and choose your deployment model (hosted API, private instance or self-hosted) based on how sensitive the inputs are.
Most of this belongs in a short policy people actually read. Our generative AI usage guidelines show what to put in one page.
What this looks like in healthcare, hiring and government
Three domains show the pattern clearly, because the consequences are visible.
Healthcare. Diagnostic support tools help clinicians when governance requires a human to confirm the finding and the dataset reflects the patient population. The value comes from triage and prioritisation, not from removing the clinician.
Hiring. The best-documented failure is Amazon’s experimental resume-screening tool, reported by Reuters in 2018 and abandoned before use: trained on a decade of past applications from a male-dominated field, it learned to downgrade CVs that signalled women applicants. The lesson is not that hiring AI is unusable, but that historical decisions are a biased target to learn from.
Public sector. Government systems face the strictest scrutiny because citizens cannot opt out. Published criteria, an accessible appeal route and consultation before launch are what maintain legitimacy.
The common thread: every case that went badly involved a system making consequential decisions with no effective human check and no monitoring after launch.
Tools and documents that make the framework real
A framework that lives in a slide deck does not survive a busy quarter. Four artefacts carry most of the weight.

Model cards give every system a one-page record: purpose, data, metrics, limits, owner. They make reviews faster because the reviewer stops asking basic questions.
Independent audits catch what internal teams stop seeing. NYC already requires them for employment tools, and enterprise customers increasingly ask.
A risk register holds known weaknesses, their severity and the mitigation, with dates. It is the single most useful document in an audit.
Governance platforms centralise approvals, inventory and monitoring once you have more systems than a spreadsheet can track. Vendors including IBM offer tooling here, but do not buy a platform to substitute for decisions nobody has made yet. Our risk management framework guide covers how this connects to enterprise risk work.
A roadmap you can start this quarter
Adoption goes wrong when it starts with a policy document. Start with an inventory instead.
- List what you already run. Every model and AI-enabled feature, its owner, the data it uses and the decisions it affects. Most organisations find systems nobody was tracking.
- Rank by consequence. Sort by potential harm times likelihood. A system that scores loan applications outranks one that autocompletes email subject lines.
- Apply controls by tier. Heavy review for the top tier, light checks for the rest. Uniform controls either block everything or protect nothing.
- Train the people doing the work. Short, role-specific training beats an annual module. Note that the EU AI literacy duty already applies, so this is not optional for EU operations.
- Review and adjust. Use post-incident reviews and monitoring data to change the controls. A framework that never changes is not being used.
Pick two or three high-consequence systems and do this properly rather than covering everything superficially. The business ethics framework approach works the same way: depth on what matters.
KPIs worth reporting
Keep the measurement set small enough that someone reads it every month.
- Fairness: outcome rates by affected group, with the trend over time rather than a single figure.
- Robustness: failure rate under stress tests, and time to recover when performance degrades.
- Privacy and security: number of incidents, time to detect, time to remediate.
- Transparency: share of live systems with a current model card and disclosure.
- Accountability: share of systems with a named owner, and how long investigations take to close.
Two rules keep these honest. Report confidence intervals on fairness gaps, so a normal fluctuation does not trigger a panic and a real gap does not hide in the noise. And set the threshold that triggers a review before you see the numbers, not after.
Tie the thresholds to risk tier. Your highest-consequence system should have the tightest limits and the shortest review cycle. For the broader business context, see how AI is changing business operations in 2026.
Conclusion
An AI ethics framework is not a statement of values. It is a set of gates, owners and records that make values checkable.
The content is largely settled. Five principles run through most published codes. Three reference models agree on what good practice looks like. The regulatory picture is clear enough to plan against: the EU sets binding duties, and US states set the rules that bind employers today. What varies between organisations is execution.
Start where the consequences are largest. Inventory those systems, give each one an owner, write down what you checked before launch, and monitor what happens afterwards. That is a framework. Everything else is documentation of it.
Found this useful?
Make SmartKeys a preferred source on Google, and our articles will surface more often in your Top Stories, AI Overviews, and AI Mode.
Add as Preferred Source